How Search Engines Organized the Web: Crawling, Indexing, and Ranking from Scattered Pages to Findable Information
In the early days of the web, the internet looked more like a sprawling filing cabinet with no labels. Personal homepages, university sites, small businesses, and hobby projects all lived online, but there was no reliable way to discover them. Search engines changed that by building systems that could visit pages, understand their structure, and decide which results were most useful. This shift is a key chapter in internet history, because it turned a growing pile of scattered pages into a place where information could actually be found.
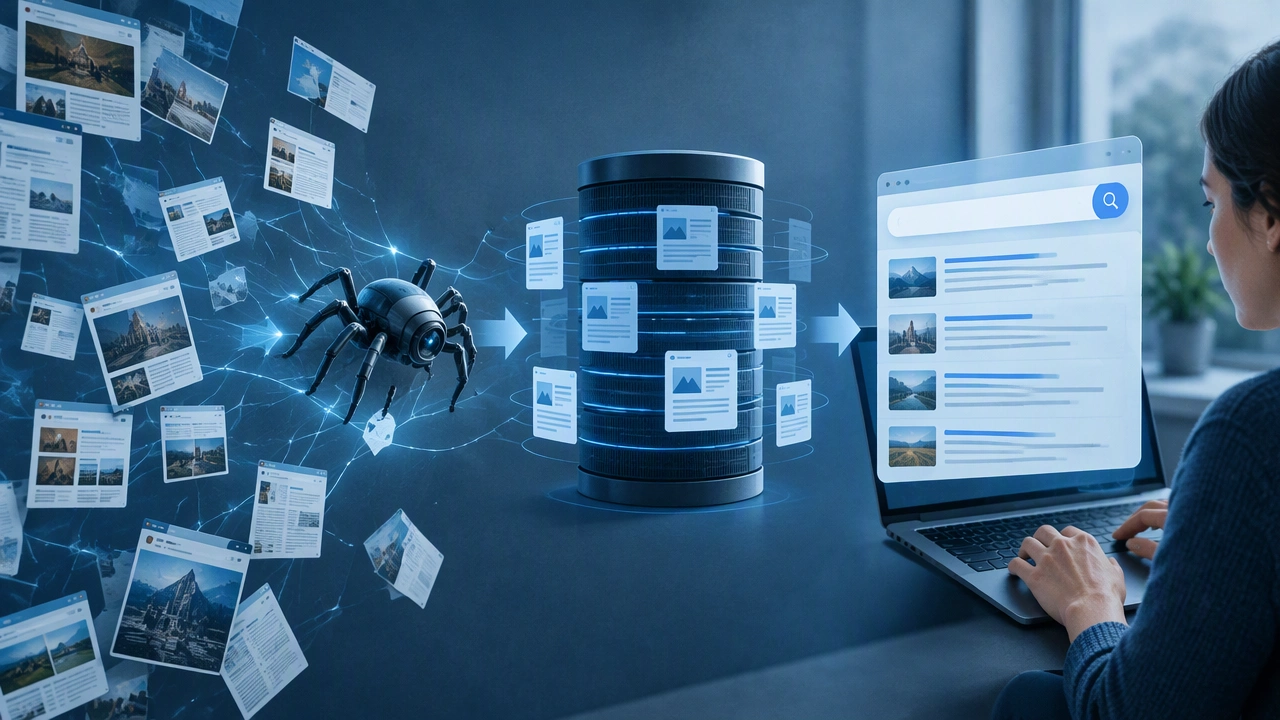
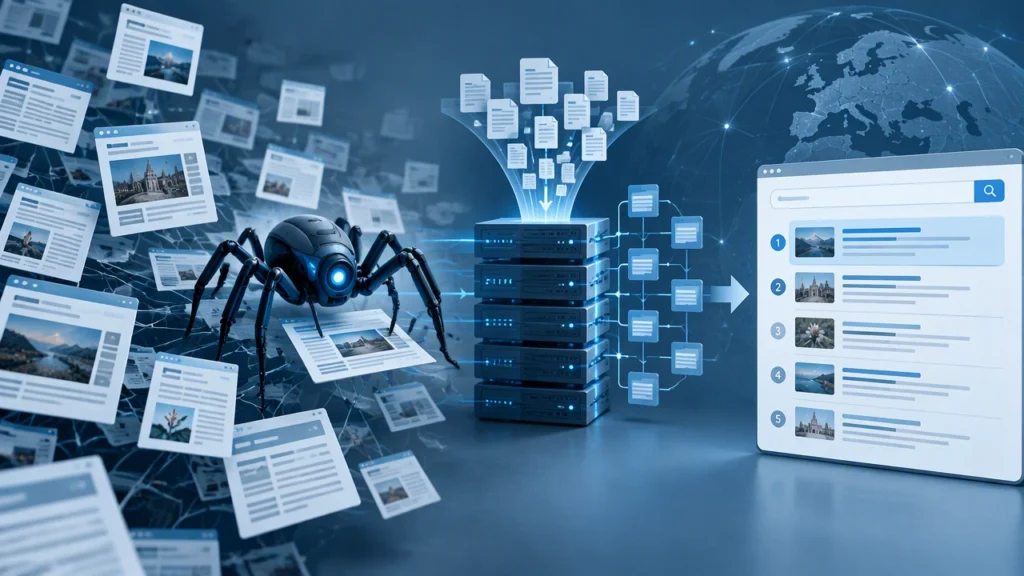
To understand how the web became organized, it helps to ask a simple question: How do search engines crawl, index, and rank websites? The answer unfolds in three connected stages. First, automated programs explore the web. Next, the content they discover is cataloged. Finally, algorithms decide which pages should appear first when someone searches. Each stage solved a real problem that existed when the web was still young.
Crawling: exploring the web one link at a time
Before a search engine can help anyone, it needs to know what exists online. That is the job of crawling. A crawler, sometimes called a spider or bot, starts with a list of known web addresses. It visits each page, reads the content, and follows the links it finds. Those links lead to new pages, which lead to more links, and the process continues across millions of sites.
This approach worked well because the web was built on links. Early crawlers did not need a central map of the internet; they could discover it by following paths that publishers had already created. Over time, crawlers became more efficient. They learned to prioritize important pages, respect rules set by site owners, and avoid overwhelming servers with too many requests at once.
Crawling also exposed a basic challenge: the web kept growing. New pages appeared every day, old pages changed, and some sites disappeared. Crawlers had to revisit pages regularly to keep their view of the web current. Without that constant refresh, search results would quickly become outdated.
How early crawlers shaped the web
Early search projects showed how powerful automated exploration could be. In the mid-1990s, systems like WebCrawler and AltaVista helped people realize that a search box could be a gateway to the entire web. The idea of programmatic discovery was not just technical; it changed user expectations. People began to assume that if a page existed, a search engine should be able to find it.
That expectation pushed publishers to think about visibility. If crawlers followed links, then clear site structures and simple HTML mattered. If crawlers read text, then meaningful titles and descriptions mattered too. Even before ranking became sophisticated, crawling created a new relationship between search engines and the people who built websites.
Indexing: turning pages into a searchable catalog
After a crawler gathers pages, the next step is indexing. Indexing is the process of organizing the content so it can be retrieved quickly. A search engine does not search the live web every time someone types a query. Instead, it searches its index, a structured collection of information about pages it has already visited.
An index stores key details: the words on a page, their position, the page title, headings, links, and other structural signals. Some indexes also store metadata, such as language or content type. This information helps the search engine understand what a page is about and how it relates to other pages.
As the web expanded, indexing became more advanced. Search engines moved beyond simple keyword matching. They began to group related terms, recognize variations of words, and understand common patterns in how people search. This made results more relevant, especially when a query did not perfectly match the words on a page.
The role of structure in indexing
HTML gave search engines useful clues. A page title often summarized its topic. Headings broke content into sections. Links showed how pages connected. Publishers who used clean, readable HTML made indexing easier, and that often led to better visibility. Over time, standards and best practices grew around these ideas, helping both humans and machines make sense of web content.
Indexing also had to deal with duplicate content, very large sites, and pages that changed often. Search engines developed ways to group similar pages, prioritize fresh content, and handle practical issues like broken links. These choices quietly shaped the web by encouraging clearer structure and more consistent publishing habits.
Ranking: deciding what appears first
Crawling finds pages. Indexing organizes them. Ranking answers the most important user question: which result is most helpful right now? Ranking is where search engines use signals to order results. Early systems relied heavily on keywords. If a page contained the exact words someone searched for, it had a better chance of appearing near the top.
That approach worked at first, but it had limits. Some pages stuffed keywords into their text without offering real value. Others were hard to find simply because they used different wording. Search engines needed better signals, and one of the most important came from the web itself: links.
From keywords to link-based authority
Links acted like votes. When one page linked to another, it suggested that the destination had useful content. If many pages linked to the same source, especially from respected sites, that source appeared more trustworthy. This idea helped search engines move beyond pure keyword counting and toward a more meaningful view of quality.
Ranking also considered many other factors. Page speed, mobile friendliness, secure connections, and clear site architecture all became signals. Search engines looked at how pages were organized, how often they were updated, and whether they provided a good experience for visitors. The result was a more complete picture of what made a page worth recommending.
Keeping ranking fair and useful
As ranking grew more powerful, some people tried to manipulate it. They created low-quality pages designed to capture traffic rather than help readers. Search engines responded by refining their systems and calling these practices spam. Over time, updates rewarded originality, depth, and trustworthiness. This back-and-forth pushed the web toward better content, even though the work of keeping results fair is never finished.
Why these three stages still matter
The basic model of crawl, index, and rank remains at the heart of how the web is organized. Even as devices, interfaces, and search habits change, the same principles apply. Publishers still benefit from clear structure. Readers still benefit from relevant results. And the web still depends on automated systems that can keep up with its scale.
Understanding these stages also helps explain why search is not magic. It is a careful process built on exploration, organization, and evaluation. Every search result reflects countless small decisions made by systems that turned a chaotic collection of pages into something people could navigate.
What this means for the future
As the web grows into new formats, including video, audio, and interactive content, crawling, indexing, and ranking will keep evolving. Search engines will continue to learn how to understand different types of information and how to present them in useful ways. The goal remains the same as it was in the early days: help people find what they are looking for, even when the web feels endless.
From scattered homepages to global libraries of knowledge, the story of search is the story of organization. Crawling explored the web. Indexing made it understandable. Ranking made it useful. Together, these steps turned the internet from a maze into a map.